After you change an agent’s prompt, a successful demo tells you about one conversation. It does not tell you which other paths improved or broke. You need tests for the actions and replies your users depend on.
This series shows how to combine recorded conversation events, model-judged criteria and varied synthetic customer turns. You will learn what each method checks and how to inspect failures instead of relying on a good-looking demo.
Three questions, one framework
The central idea — and the thing most teams get wrong — is that “is the agent good?” is actually three different questions:
| Question | Answered by | Character |
|---|---|---|
| Did the agent do the right thing? | structural assertions — facts about the tracker | Exact, repeatable, no judge noise |
| Did it handle the user well? | criteria — scored by an LLM judge | Tolerates paraphrase; costs variance and money |
| Which paths do varied synthetic turns explore? | the LLM user-simulator | Produces synthetic turns from scenario instructions |
These conversations are simulated; real-user acceptance needs separately observed sessions.
Some assertions also ask a model to judge relevance or grounding. Check the assertion type before treating a result as deterministic.
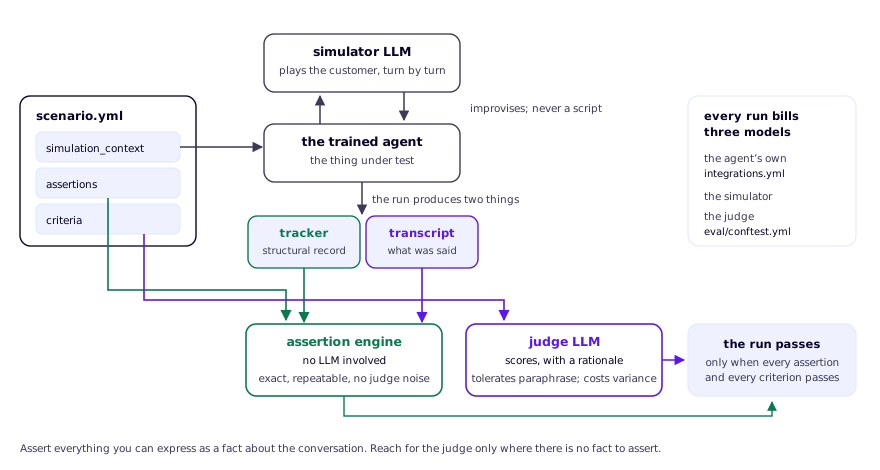
On Rasa Mantle all three live in one framework: you author scenarios, a simulator LLM plays the customer, and the completed run produces structural checks of recorded events plus model judgments from generative assertions and natural-language criteria.
Why a simulator at all? Because Mantle skills are not scripts. A
skill.md gives the model intent and constraints, not a dialogue path — so a
test file of hard-coded user turns exercises one path through a system whose
defining property is that it improvises paths. The simulator meets the agent
on its own terms. The rule that keeps the whole thing honest underneath:
Assert everything you can express as a fact about the conversation. Reach for the judge only where there is no fact to assert.
Teams that invert this end up with a slow, expensive, flaky suite that measures their judge’s mood as much as their agent’s behaviour.
The two paths do not read the same thing, and that is the detail worth carrying into Chapter 2:
The agent is a fixture, on purpose
The companion project ships a two-skill retail-banking assistant with hard-coded data. It is deliberately boring, and the boringness is a design decision worth stealing: a failing scenario should always mean the agent changed, never that the data moved. Wire an eval suite to a live database and every flaky run becomes a debugging session about the data. The harness is the subject here; the agent is the lab rat.
The chapters
| # | Chapter | The question it teaches you to answer |
|---|---|---|
| 1 | Set up the lab | Does it run on my machine, and what does a passing suite look like? |
| 2 | Assertions | Which checks are deterministic, and which use a judge? |
| 3 | The simulator | Does the agent survive a customer who never read your script? |
| 4 | The judge | Was the answer grounded and relevant — and what do those words mean? |
| 5 | What your eval cannot tell you | When is a green run evidence, and when is it noise? |
Chapter 5 is short and it is the one to not skip. An eval that oversells itself is worse than no eval, because it launders a guess into a number.
Before you start
- Python 3.11 or 3.12, uv, and git.
- A free Rasa Pro Developer Edition licence and an OpenAI API key. You need both from Chapter 1 — evaluating an agent requires running one.
- A coding agent that can drive an MCP server (Claude Code, Cursor, or Copilot) — scenarios are run through Rasa’s MCP server, per the simulation docs.
- A cost note up front, and it is blunter than it used to be: a simulated run can use three LLMs — the agent’s own model, the simulator, and the judge. Cost depends on the selected models, conversation length and repeats; this tutorial has no measured per-run price. Start with small batches and record provider usage before deciding how many runs to acquire.
The companion installation targets rasa-pro==3.21.0.dev5. The
compatibility report distinguishes current deterministic
checks from live model runs. Following the companion pattern, claims about
engine behaviour cite the source file they refer to. When you
wonder “but how does it actually score that?”, the file and line are right
there.